Evaluation & Testing
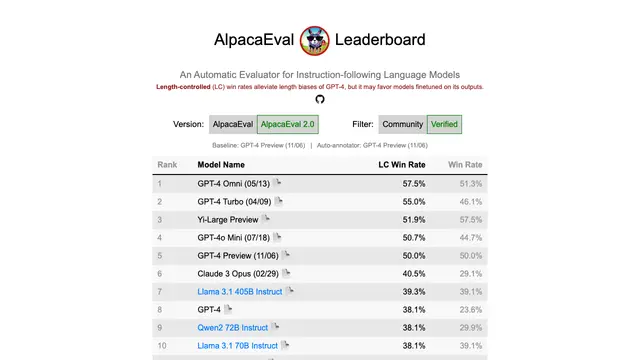
Frameworks and platforms for scoring prompt and agent output: eval harnesses, LLM-as-judge tooling, benchmarks, red teaming and observability.
Questions
Frequently asked questions
What counts as evaluation & testing?
Frameworks and platforms for scoring prompt and agent output: eval harnesses, LLM-as-judge tooling, benchmarks, red teaming and observability.
What are evaluation & testing?
Frameworks and platforms for scoring prompt and agent output: eval harnesses, LLM-as-judge tooling, benchmarks, red teaming and observability.
Do I need a tool for this?
Solo users often do fine with a text file. Teams shipping prompts to production usually want versioning and evaluation. Start with the free tier of a tool in the category.